
Tuesdays usually arrive with something to watch or listen to. This week, I wanted to send the invitation before the finished episode.
On Thursday, Prasanna Vijayanathan and I are recording the next Agentic Engineering podcast live because a conversation about unexplained agent failures should include the people encountering them.
You’ll be able to bring your questions, edge cases and puzzling traces into the room—and help shape where the conversation goes.
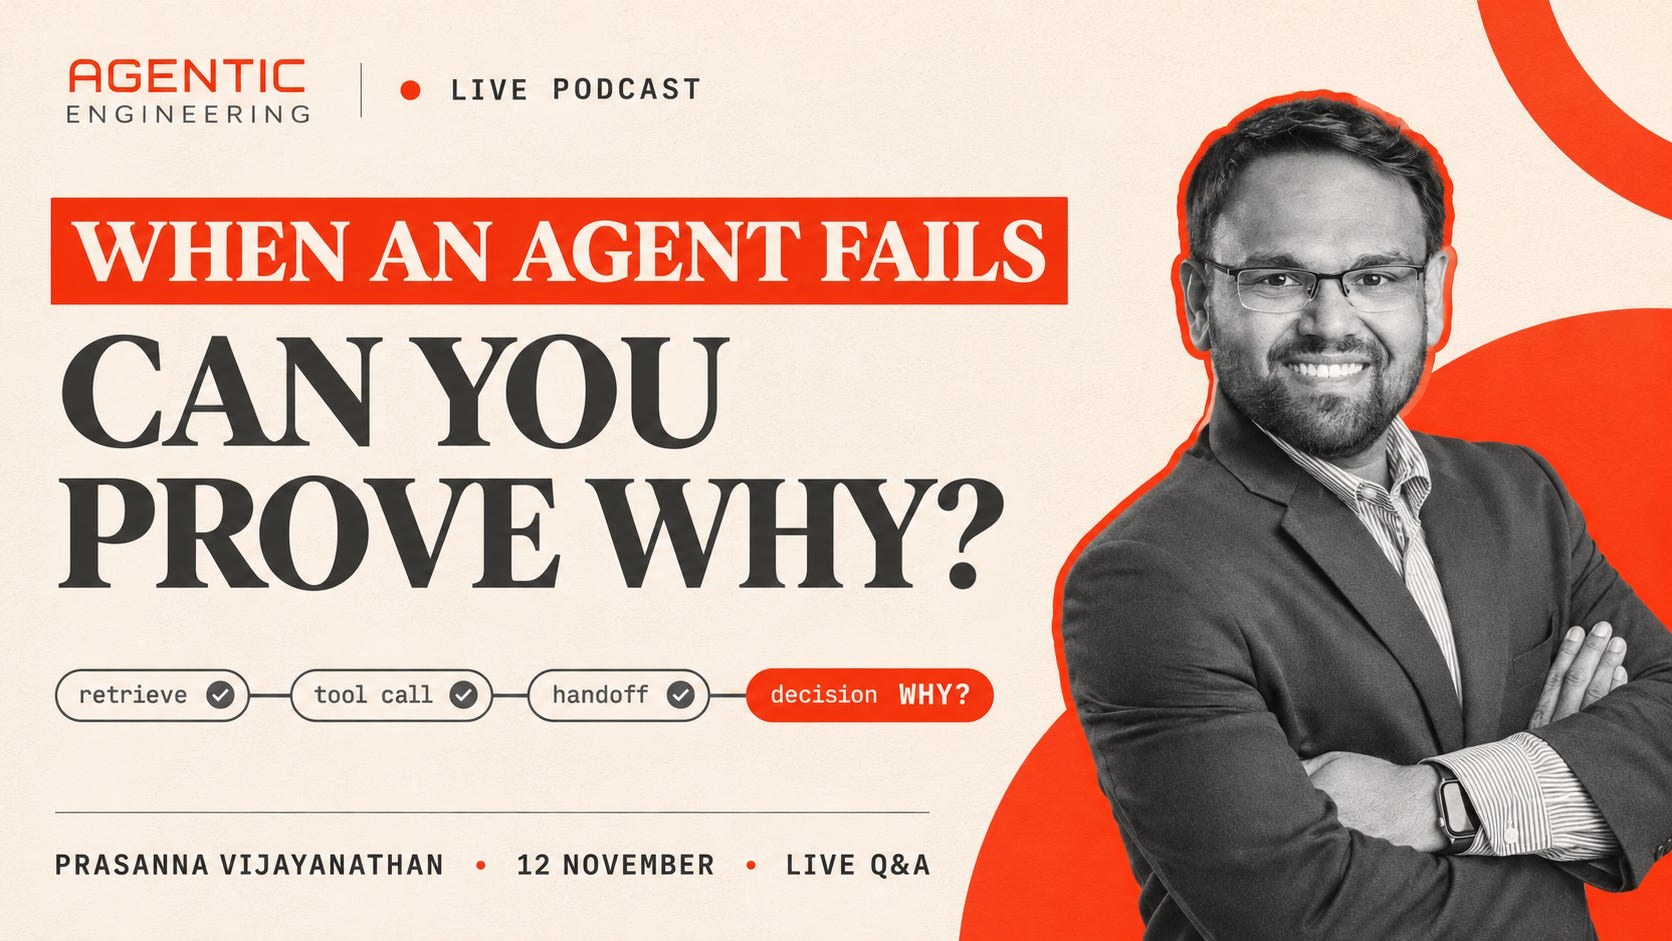
A clean trace can still hide the failure
The model ran. The tools worked. Every handoff completed. The result was still wrong.
A trace shows the path. It does not prove the cause.
Why Prasanna?
At Netflix, Prasanna works with observability systems processing upwards of 38 million logging events per second. His book, Fairness in Generative AI, examines what standard reliability metrics miss: a technically healthy system can still fail the people using it.
That makes him particularly well placed to connect runtime evidence with accountability.
The questions traces cannot answer
Is a correct result still a success if the agent took a broken path?
Where do you pin the failure when the model, context, memory, tools and a human all contributed?
What must you preserve to reconstruct a non-deterministic run—and what is too sensitive to retain?
Can a knowledge graph establish cause, or only surface correlations?
How do you detect fairness drift while every reliability dashboard remains green?
When does human oversight become a rubber stamp?
And if you cannot observe everything, what should you measure first?
Join us live
Thursday, 12 November
9:30–10:30 PM GMT+5
If you have an agent trace that explains everything except the failure, bring it.
That’s it for this one. We’ll pick up the conversation next week.
Until then, keep building.
Tanya D’cruz
Editor-in-Chief